

TheWhiteBox · Independent AI analysis
GILL, a New Chatbot that Generates Both Text and Images Simultaneously
Sign in or subscribe to keep reading ↓
🏝 TheTechOasis 🏝
Talking to an AI chatbot that generates impressive text like ChatGPT is really cool.
Now, talking to an AI chatbot that generates text AND images is way cooler… and something ChatGPT doesn’t offer.
But GILL, Carnegie Mellon University’s new AI chatbot, does.
And you can see it with your own eyes below:
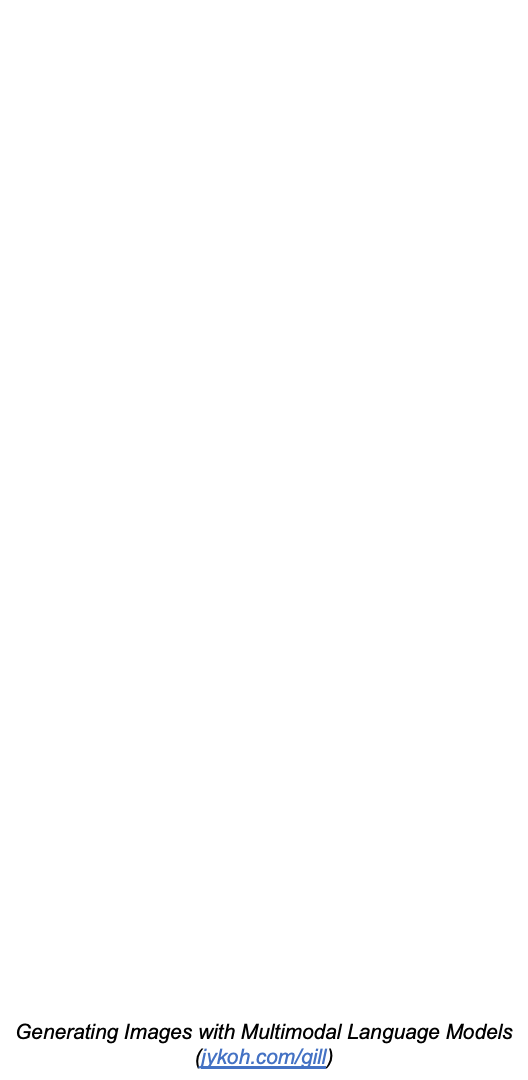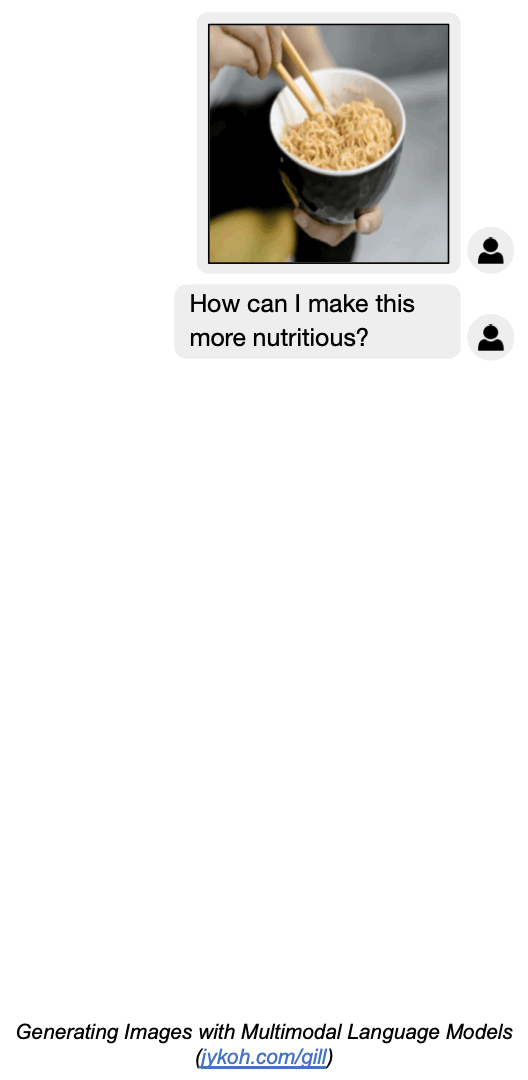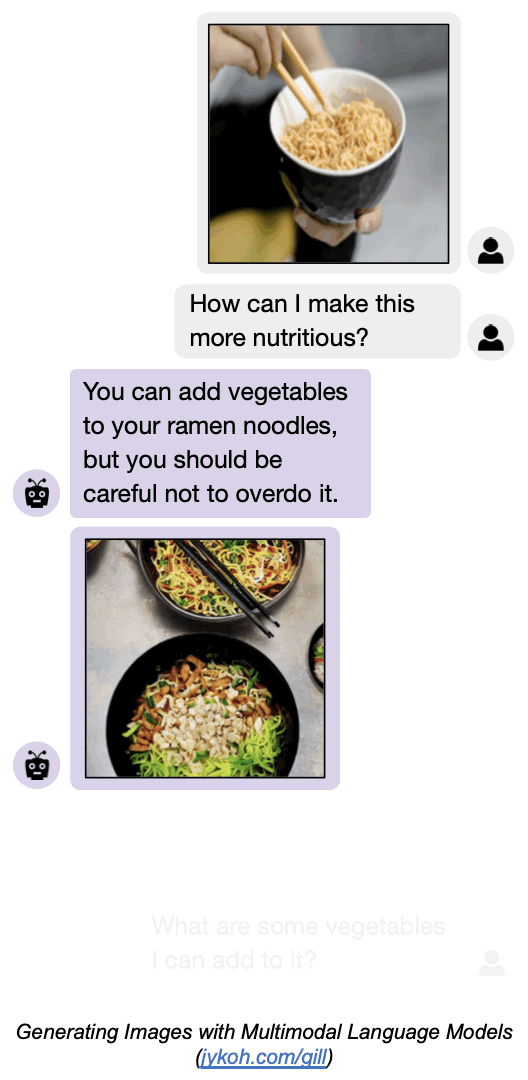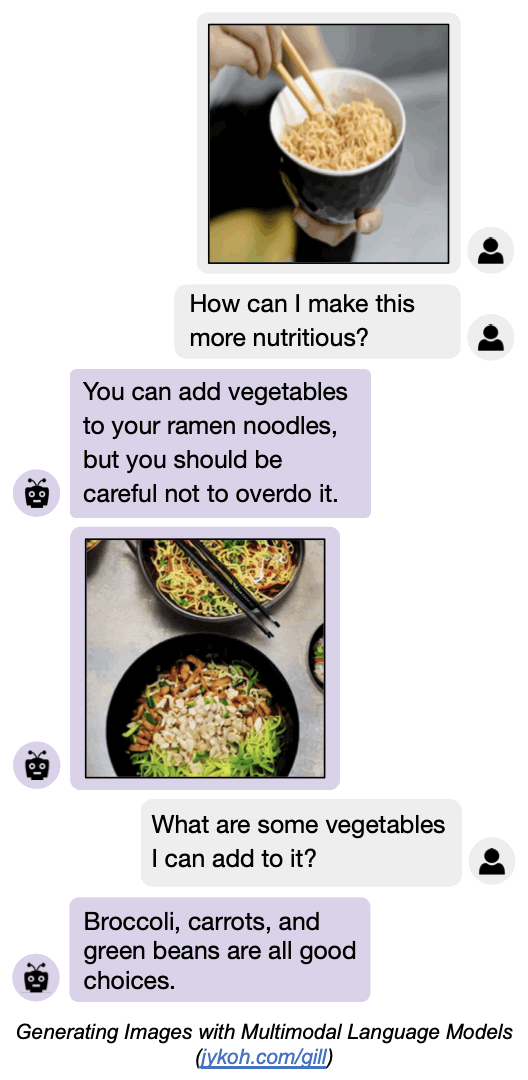
GILL is the first-ever AI chatbot that’s capable of understanding both images and text while also being capable of producing both images and text.
And if being a first in the most innovative industry in the world isn’t already impressive, it was also cheap as hell to train.
But how does GILL work?
When Text Meets Images
Creating an AI model that works well in one modality (text, images, etc.) is already pretty challenging. But creating a model that works across several modalities is something rarely seen.
In fact, when GPT-4 was presented to the world, everyone was amazed that one unique model was capable of understanding text and images as GPT-4 did.
And even though its image processing features aren’t released yet (you can check them here), GPT-4 is only multimodal when it comes to processing data, not generating it.
GILL, on the other hand, not only can process both modalities, but it can also generate both, as seen in the previous GIF.
But to achieve this, they had to overcome an important challenge.
Making Images and Text ‘Talk’
Even though we humans are capable of understanding both images and text naturally, this isn’t an easy concept to explain to machines.
To do so, we transform text and images into vectors—called embeddings—that extract their meaning while allowing machines to treat them.
This embeddings represent the model’s understanding of our world, where vectors that represent similar concepts are grouped, and those that don’t are separated.
For instance, if we take the visual example below of a text-only embedding space like the one ChatGPT has, concepts like “A little boy is walking” and the same but “running” are close together, while separate from “Look how sad my cat is”.

If you ever wondered how machines understand our world, there you have it.
But the problem is that every model has its own representation of our world, which means that ChatGPT’s embeddings (text-to-text) aren’t valid, for instance, for Stable Diffusion (text-to-image).
This is a problem because if we want a model to process and generate multiple modalities at once, we need to create an embedding space that groups embeddings from all modalities into one unique space.
And that’s precisely what GILL does.
When Maps Are The Solution
GILL does five things:
Process text
Process images
Generate text
Generate
Retrieve images
To do this, it needs to be capable of:
Processing images and text simultaneously
Decide when to output a text or an image
When outputting images, decide if it needs to generate or retrieve the image from a database
To pull this off, the researchers did the following:
To process images and/or text, they assembled a transformation…
Enjoyed the introduction? Subscribe or sign in to continue with this edition.
TheWhiteBox · Subscriber access
Keep reading.
Already subscribed? Sign in with your newsletter email.